Large-model serving
Build a dedicated inference service for larger models, with precision and throughput validated against your own requests.
Kulper AI System · DATACENTER AI
Your own AI, at datacenter scale.
TALK TO KULPER
Talk to our team about your models, performance targets and installation site. We'll work through the configuration, current availability and support with you.
We confirm qualified components, rack space, power, cooling, networking and delivery as part of your project quote in $ USD. Ask us about purchasing, financing or leasing.
Your quote specifies the selected hardware's warranty, onsite service options, response terms and regional coverage. Service levels are agreed for your installation, separately from optional model management.
Warranty & service detailsFrontier B300 · OVERVIEW
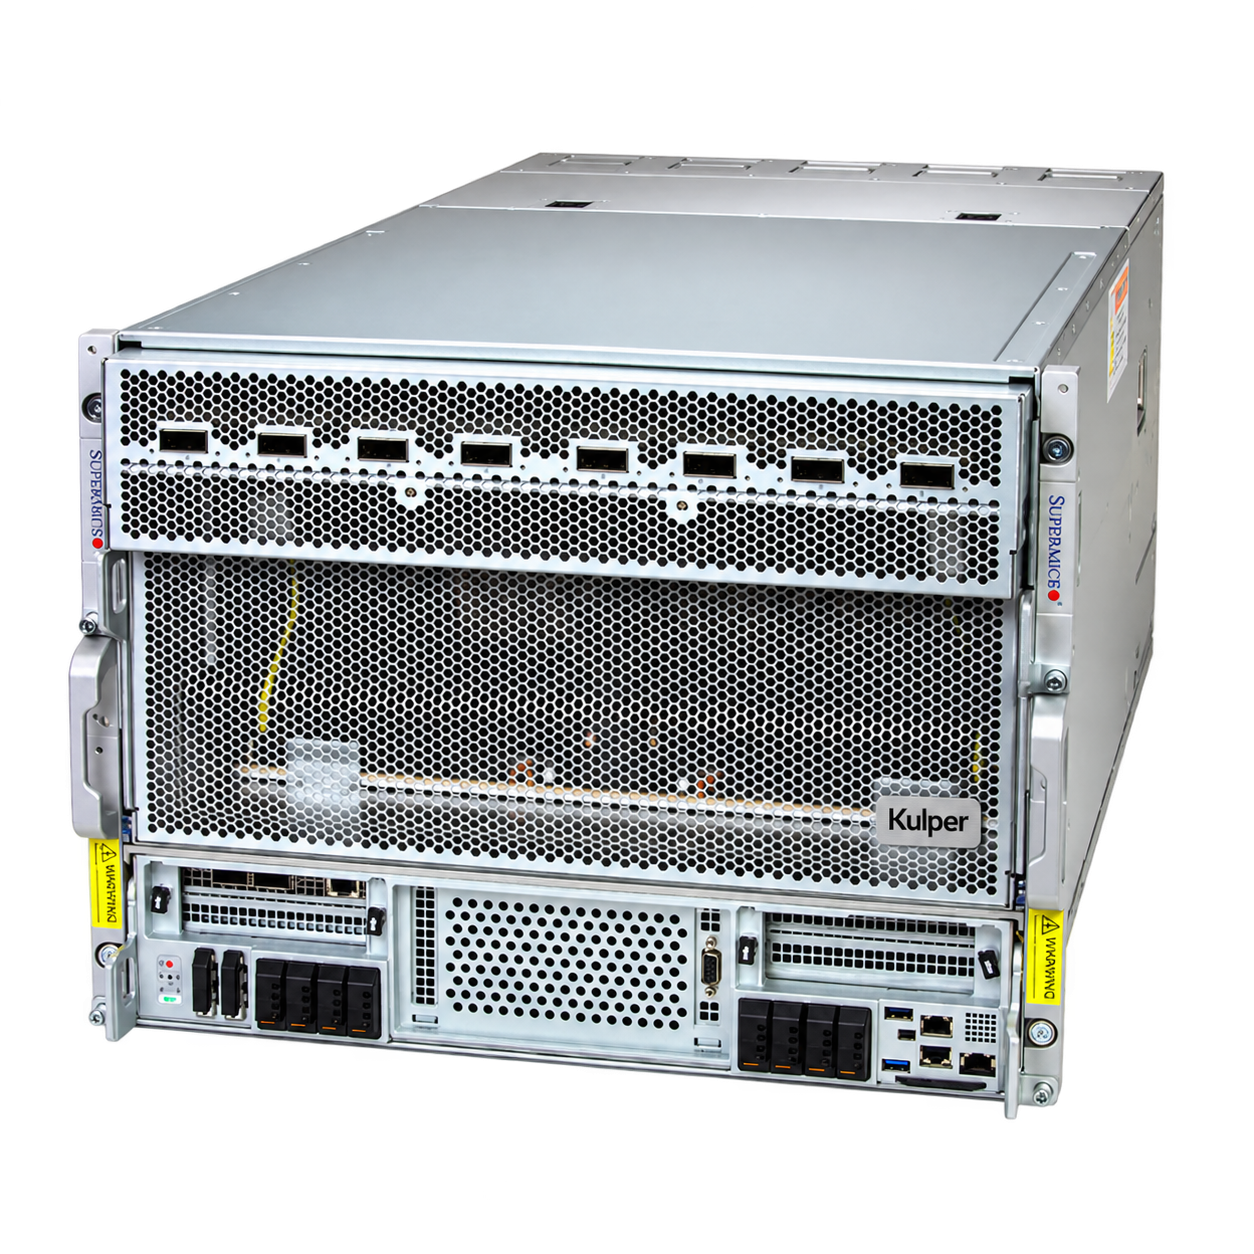
Frontier B300 combines an eight-GPU NVIDIA HGX platform with integration and support from Kulper AI Systems. We plan the build around your model, context length, concurrency and installation site, then test the agreed workloads before handover.
Build a dedicated inference service for larger models, with precision and throughput validated against your own requests.
Scope model adaptation and training jobs around dataset size, GPU memory and the required software stack.
Plan capacity, access and workload scheduling for multiple teams or business processes on your own infrastructure.
THE HARDWARE
These are proposed Kulper AI System specifications. The final platform, qualified components, firmware and service package are confirmed in your quote. Kulper AI Systems handles configuration, software integration, acceptance testing and installation planning.
NVIDIA's HGX reference architecture lists up to 288 GB per GPU / 2.3 TB total. We use the lower datasheet figures above for planning and confirm available model memory on the supplied system.
Model fit still depends on precision, context and concurrency. NVLink supports communication between GPUs; software must distribute the workload. We validate your models before committing to performance targets.
At 1,100 W maximum TDP per GPU, eight GPUs alone total 8.8 kW. CPUs, memory, networking and fans add to this. This is not a whole-server power or cooling estimate; the quote includes a site plan for the agreed configuration.
We check the completed system against the NVIDIA HGX reference design, including memory bandwidth and channel population, PCIe topology, networking and secure boot / TPM requirements.
NVIDIA HGX reference requirementsSSD figures are total raw capacity before formatting or RAID. Model fit and performance depend on quantization, context length, and concurrent use.
FROM HARDWARE TO WORKING AI
We assemble and test the hardware, preload your chosen models and confirm your delivery date. Choose UPS shipping where suitable, or discuss delivery for a larger rack system. Install it yourself with our setup guide, or have our team connect the system, install clients and help assign user permissions. Shipping and installation work are itemized in your quote.
Choose ongoing model updates, maintenance, and support, or a configured system handed over to your team. Management is quoted separately.
Explore Kulper ControlHardware coverage follows the applicable component and platform manufacturer terms. Your quote identifies the supplied parts, coverage periods and how our team coordinates a repair or replacement.
Onsite service, labor, shipping, response times and extended coverage are agreed for your location before you order. Any service contract required by the selected platform is included in the proposal.
How hardware coverage worksDiscuss purchase, finance or lease options directly with our team. Terms and availability are confirmed for your project.